Blog / Interlinear

Make Your Own Interlinear with Jev

Try the interactive interlinear aligner.

This tool lets you hand Jev (a new AI model) a translation of a Bible verse. It aligns the translation with the original Greek or Hebrew in seconds, about 30x faster than using a frontier model for the alignment. The interface also lets you correct any errors in the alignment by hand and export the alignment as JSON for your own purposes.

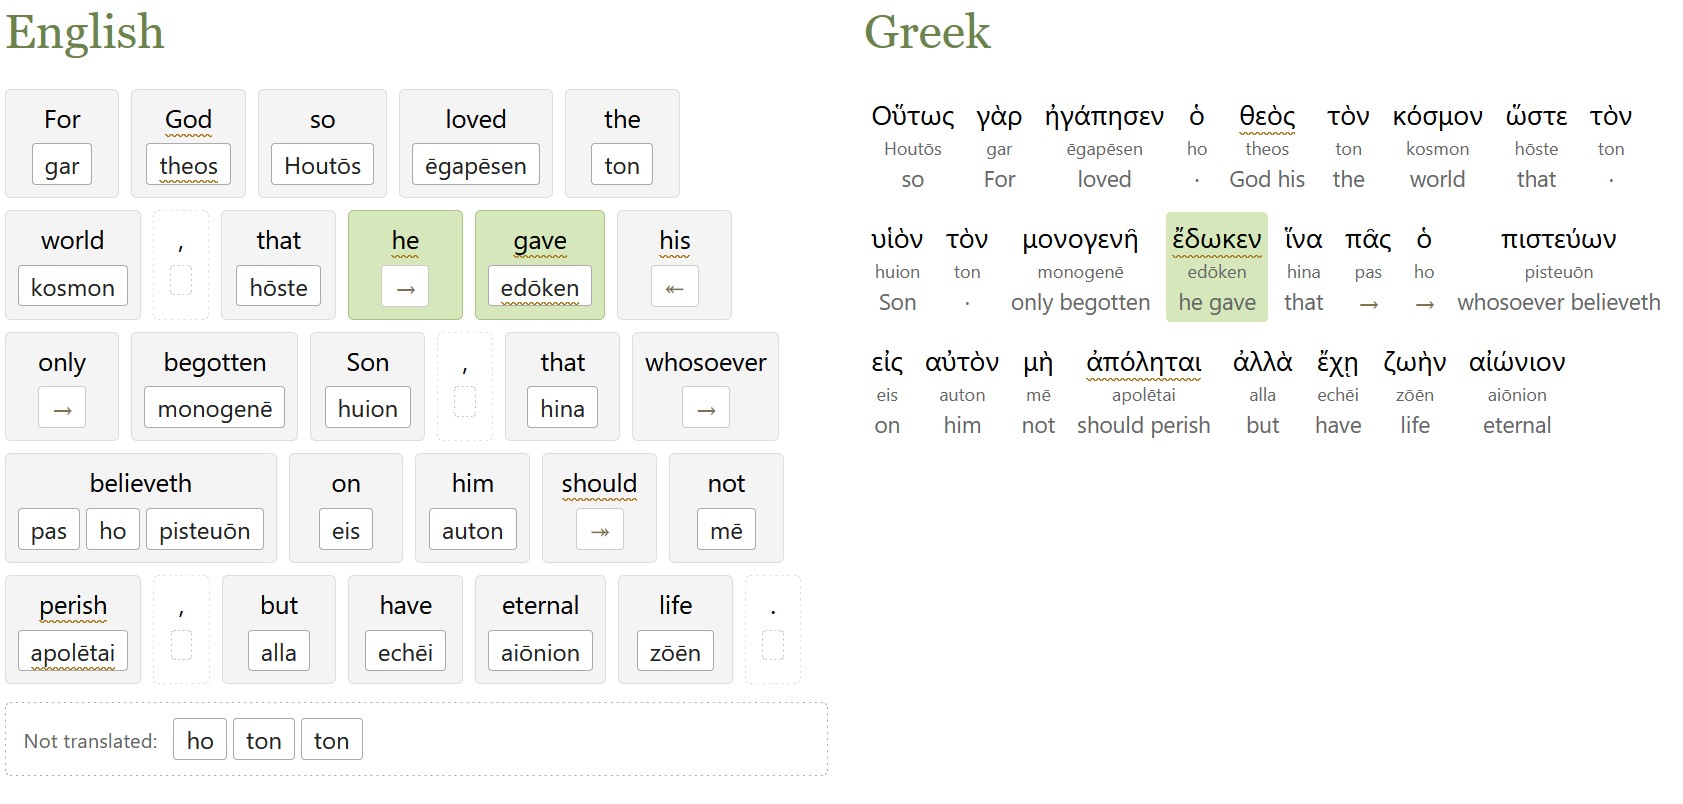
A screenshot of John 3:16 in the interlinear interface shows how you can align its text with the Greek.

When building an interlinear for the ASV Bible, I mentioned how each chapter took 30+ minutes to align using a frontier model (or about two minutes per verse). In my testing, Jev creates a verse-level alignment that agrees with the final ASV interlinear on 80% of tokens, in seconds, for just under 1 U.S. cent per verse (on average).

It works for any English translation of a verse; for example, you could create your own translation and ask for an interlinear alignment. It also appears to work decently on non-English languages, though I only tested Spanish on a single verse.

The code reformulates the ASV interlinear alignment rules into 179 focused policies that Jev can apply to any verse. The ASV rules (Hebrew and Greek) are widely reusable for other projects; if you’re thinking of doing an interlinear alignment, I’d encourage you to consider them as a starting point.

This aligner is good enough to use as a first-pass interlinear for Greek or Hebrew, or if you need something quick, but I wouldn’t rely on it without further review. You could take its output and send it to a stronger, slower LLM for final polishing, for example.

It works better on word-for-word translations than on thought-for-thought, though it does what it can.

If you want to use Jev for this purpose at scale rather than interactively, I also published the code that does this alignment.

Posted in AI, Code, Interlinear

Building an Interlinear Apocrypha in two days for $50 with AI

Try the Interlinear Apocrypha.

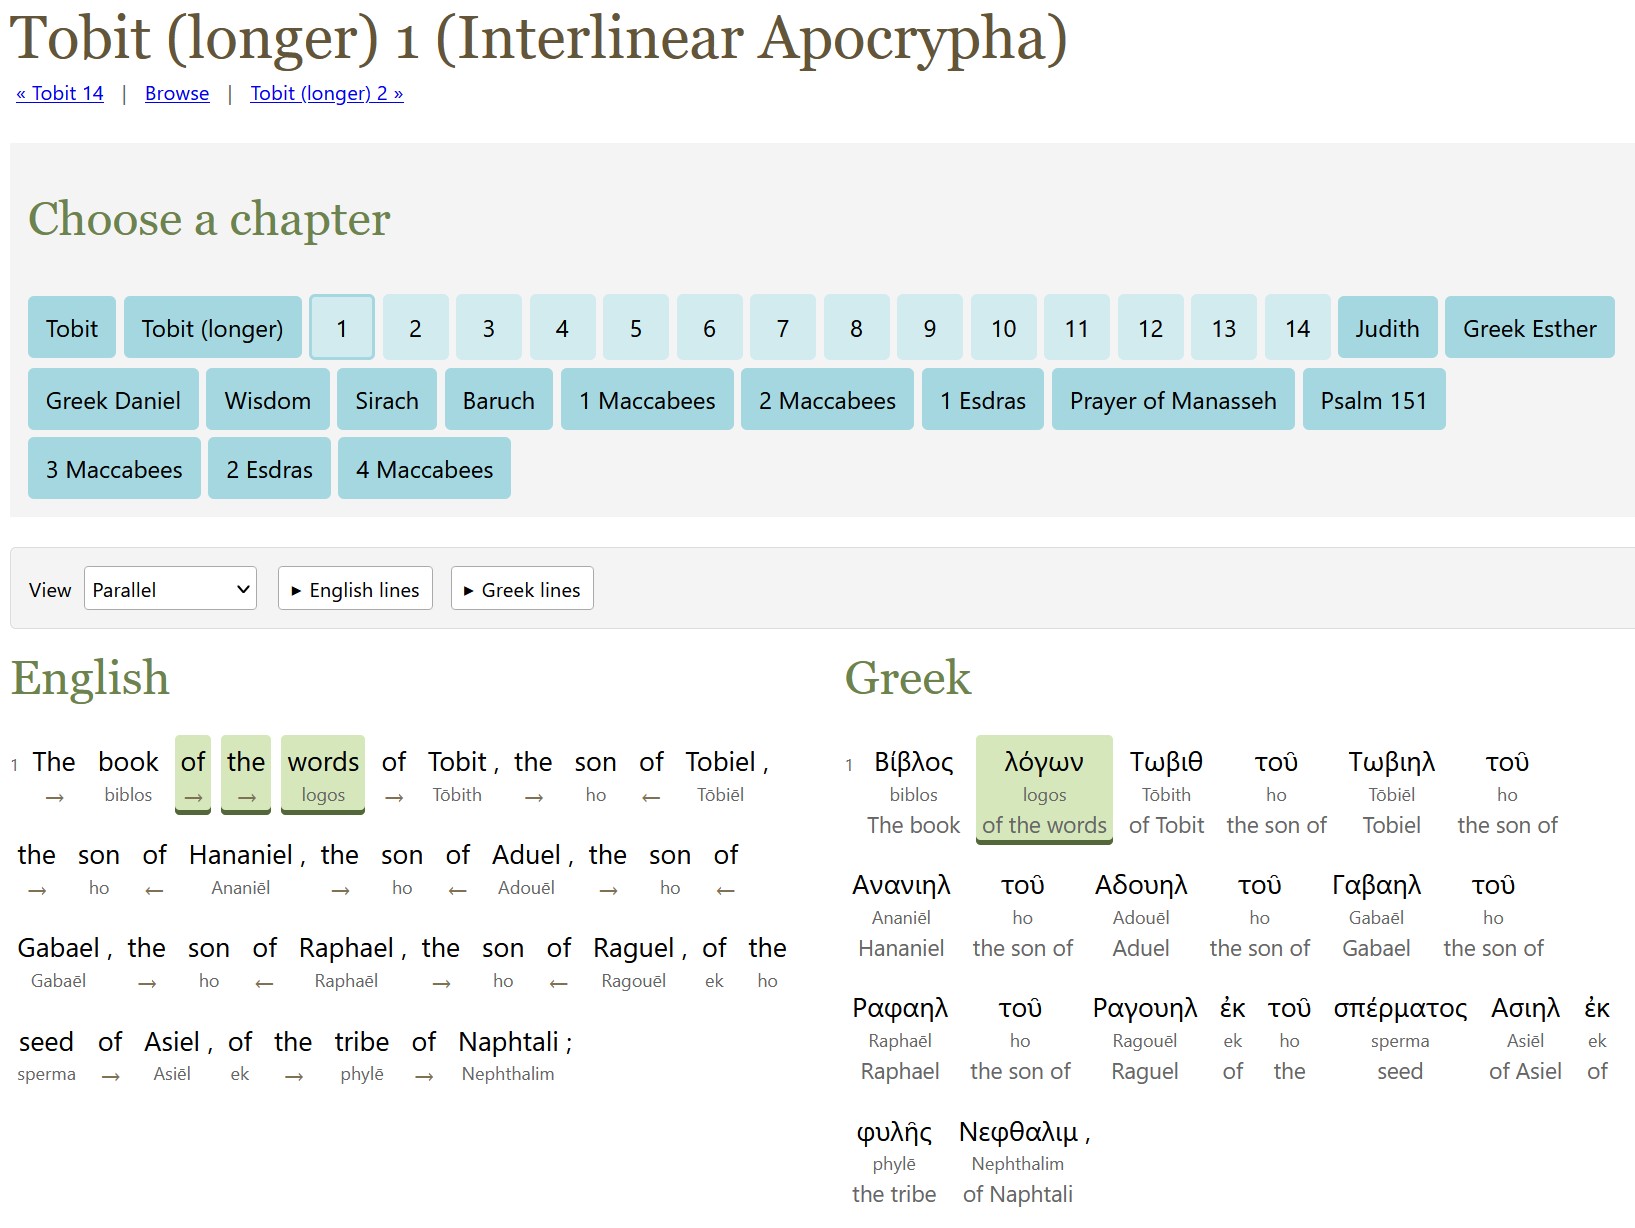
A screenshot of longer Tobit 1 in the interlinear shows highlighting between the English and the Greek.

The method to produce last week’s ASV interlinear also works for the Apocrypha (or Deuterocanonicals), which is mostly in Greek.

Unlike with the ASV alignment, this project doesn’t try to align alternate readings in the original languages; I didn’t think it was worth the processing time, though I did include the apparatus from the source texts.

The English translation is the World English Bible (WEB) because it has a translation of the Apocrypha and is freely available. (The ASV translators didn’t translate the Apocrypha.) The only exception is the longer Tobit (did you know there were two Tobits? I didn’t!), which uses D. C. Simpson’s 1913 translation because WEB only translates the shorter Tobit.

GPT-6 Astra did all the alignment work. It used a week’s worth of Pro 20x Plan tokens (thus the $50 cost). I later expanded the scope to transcribe the source apparatus (alternate manuscript readings, mostly), as described below, which cost another $15.

I used latinCy to generate the Latin parsing, with a review by Astra.

Here’s the output:

  1. The interlinear/reverse-interlinear interface, which lets you explore both English-first and original-language-first interfaces.
  2. A Git repo containing:
    1. The WEB English text tagged to the original languages (except for longer Tobit, which aligns Simpson rather than WEB).
    2. Greek and Latin text tagged to English. The versification here matches the originals rather than WEB. For example, Letter of Jeremiah is a separate book rather than WEB’s Baruch 6.
    3. Raw alignment data. As with ASV, these files are mostly the LLM talking to itself. I didn’t bother to include the scripts, which are substantially similar to the ASV ones.

Recreating the text of the Apocrypha

The Apocrypha text used is Rahlfs (1935), which the NRSVue translators say they used for most books. The Latin source text for 2 Esdras is from Bensly (1895).

While the main text was already digitized (mostly) correctly, I also decided to digitize the apparatus (which you can find in the USX files and in the original-language side of the HTML).

Here was my process for each page:

  1. GPT-6 Luna identifies the page regions in the page scans (header/footer vs. main text vs. apparatus). I ran three independent agents and took the union of the three.
  2. GPT-6 Sol transcribes the text. I used two agents for independent transcriptions. GPT-6 Luna wasn’t good enough to provide reliable transcriptions.
  3. GPT-6 Astra reconciles the Sol transcriptions and does any further work to finish the page.

It took about 30% of a week’s tokens on ChatGPT Pro 20x plan to parse around 550 pages, suggesting a potential processing rate of about 1,800 pages per week using this method. (This 30% was on top of the week’s tokens I spent on the alignment itself.)

Surprises

I asked GPT-6 Astra to reuse the ASV scripts, and I learned much later that it only sort-of complied. It missed a lot of details in adapting the scripts, which it had to reimplement later. My impression is that it rewrote these scripts from scratch instead of reusing what already existed.

About 92% of the Greek text (total words, not unique words) was able to have a Strong’s number assigned to it, thanks to TBESG. It probably could have found more, but it was spending a lot of tokens for diminishing returns.

Posted in AI, Code, Interlinear

Building an Interlinear for the ASV Bible in six weeks for $300 with AI

Try the ASV interlinear.
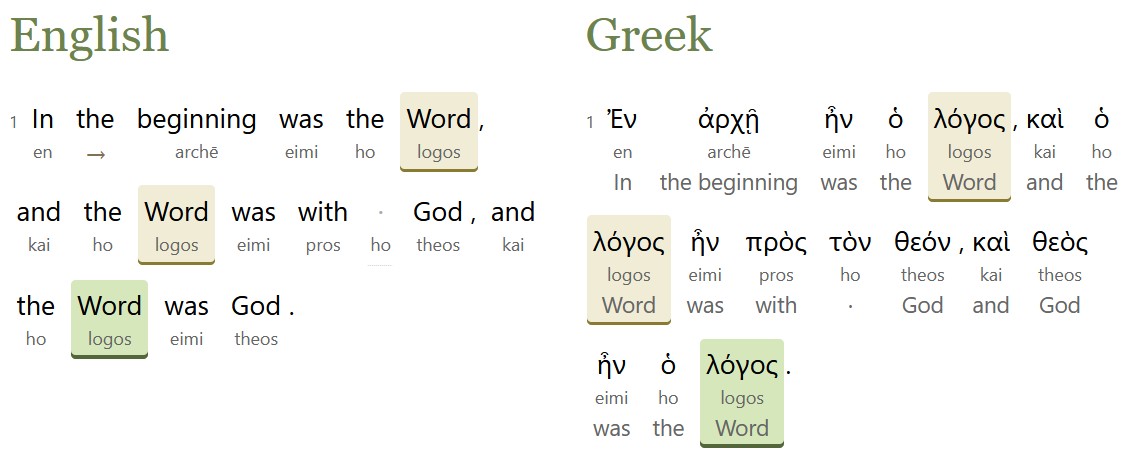
A screenshot of John 1 in the interlinear shows highlighting between the English and the Greek.

AI models are now smart enough to align English Bible translations with the original Hebrew and Greek, so why not make an alignment?

Starting with the English text of the American Standard Version (ASV) Bible from 1901, which is in the public domain, Opus 5, GPT 5.6 Sol, and GPT 6 Astra created an interlinear alignment, matching up the Hebrew and Greek original with the ASV’s modern(ish) English.

Here’s what they produced:

  1. The interlinear interface, which lets you explore both English-first and original-language-first interfaces. It also lets you see where the ASV departs from the KJV’s underlying text (155 verses).
  2. An ASV English text tagged to the original languages.
  3. A Hebrew and Greek text tagged to the ASV English. This text hypothetically reconstructs the eclectic text used by the ASV translators; textual variants that appear to have been chosen by the translators serve as the main text.
  4. Data and scripts that let you adapt this alignment process to your own text. If nothing else, the hard-won alignment rules, which went through hundreds of revisions over the course of this project and which cover all the tricky situations encountered during it, can serve as the starting point for your own alignment. LLMs love to talk about what they’re doing, and this repo records alignment reasoning down to individual verses.

Maximalist alignment philosophy

Perhaps most controversially, this project adopts a maximalist alignment philosophy, where it tries to align as much as possible, including italicized words that the ASV translators indicated as added. There are 6,250 such italic words in the ASV:

  • 3,303 are tagged as “added,” consistent with the ASV translators’ view.
  • 2,584 are tagged as part of a phrase with a different headword (the most-important word in a phrase).
  • 363 are tagged as headwords. For example, “those lands” in Judges 11:13 is translating the Hebrew pronoun for those. This alignment puts the phrase head on “lands” because it’s the most distinctive part of the phrase.

Process

Each chapter went through a three-step process:

  1. Align. The AI preps the data and does a first-pass alignment for each verse. It’s provided the alignment rules and the source text.
  2. Review. The AI looks at each verse and assesses whether the alignment is correct.
  3. Reconcile. The AI takes a larger view of the chapter, identifying inconsistencies or common themes and deciding whether to create new rules based on what it learned during this chapter.

Each chapter took about 40-60 minutes to run. Psalm 119 (the longest chapter in the Bible) took 90 minutes.

Managing cost

The hardest part of this project was managing token budgets. At first, I was parsing individual verses, which is the best way to achieve isolated alignments and reviews. But this approach exhausted my token quotas too quickly. So I switched instead to handling a full chapter at a time, which seemed to be the best balance of cost and performance.

Using this process, Claude Max or ChatGPT Pro 20x plan can process about 200-300 chapters per week before exhausting quota. ChatGPT is about 50% more efficient than Claude in terms of the number of chapters it can process per week. It took six quota-weeks to process these chapters, which is how I arrived at a $300 cost. (Traditionally, an interlinear would cost $50,000-$100,000 to produce.)

The token list prices are much higher than what I paid:

Step List Price
Align $2,300
Review $1,900
Reconcile $3,600
Total $7,800

So a 20x plan netted a 96% token discount off list prices.

I spent 100 million input tokens, 120 million output tokens, and 2.1 billion cached input tokens. With cache writes and some additional processing, the total token usage was about 2.5 billion tokens.

I also tried DeepSeek v4 and GLM 5.3, neither of which produced good results. Gemini 3.7 Flash produced fine results on alignment, but its batch API didn’t support structured outputs, which made it useless for this purpose.

Sources

This project worked from several open datasets:

  • SBLGNT, which served as the base Greek text. The variant readings in its footnotes supported 340 verses (out of just under 8,000 in the New Testament) where the ASV translators departed from the SBLGNT’s critical text (in part because the critical text is modern, while the ASV dates from 1901).
  • MACULA Hebrew and Greek for parsing data.
  • OSHB for the WLC text and verse-number differences between the Hebrew and the ASV.

I’m aware of two existing ASV alignments: Logos (2020) and STEP Bible by Wade Masfield (2013). I validated two chapters against the STEP alignment and one chapter against an NASB alignment to confirm that the AI output was sane, but I didn’t consult existing copyrighted alignments beyond these validation chapters.

Surprises

This project used an open human alignment as a gold standard. However, this data only altered two word-level alignments in the entire Bible. It added a lot of overhead to the process, since the AI mostly talked about how it disagreed with the reference because of differences in alignment philosophy. It turned out to be wasted overhead. The English glosses attached to the Hebrew and Greek mitigate this finding somewhat.

Far and away, this finding was the most-surprising part of the whole process for me: models are smart enough to do the alignment on their own, and a gold-standard, existing alignment reference is just a distraction to them, at least for this workflow.
Posted in AI, Code, Interlinear